Ontology-Driven Data Integration for Enterprise Systems
 Marcus Webb
In short: a shared ontology, such as the Common Core Ontologies, replaces brittle point-to-point data mapping with one semantic model that every system maps into once. Instead of each pair of applications negotiating its own field-to-field translation, every source expresses its records as instances of the same classes and relations, so new systems join the graph faster and existing connections survive schema changes with far less rework.
What Is Ontology-Driven Data Integration, and Why Does It Matter for Enterprise Systems?
Ontology-driven data integration means building a formal, machine-readable vocabulary of classes, relations and constraints, and mapping every participating data source to that vocabulary rather than to each other directly. The vocabulary is the ontology. In an enterprise setting, that typically means an upper ontology such as Basic Formal Ontology (BFO) supplying domain-neutral top-level categories, with a mid-level suite such as the Common Core Ontologies (CCO) specializing those categories into reusable classes like Information Content Entity, Agent, or Act.
The reason this matters for enterprise systems specifically is scale. A single integration between two applications can be handled with a hand-written mapping script and nobody notices the technical debt. The problem compounds once an organization runs dozens of systems — CRM, ERP, asset management, logistics, HR, analytics platforms — and each new connection multiplies the number of pairwise mappings that must be written, tested and maintained. An ontology turns that quadratic problem into a linear one: each system maps once, to a shared model, instead of once per pair of systems it needs to talk to.
Where Traditional ETL and Schema-Mapping Integration Breaks Down
Most enterprise data integration today is still built on extract-transform-load (ETL) pipelines and direct schema mapping: a script reads a column from System A, transforms its format, and writes it into a column in System B. This works well enough for a handful of connections, but it has three structural weaknesses that show up as the data estate grows.
First, mappings are pairwise and do not compose. A mapping from System A to System B carries no reusable knowledge toward a mapping from System A to System C — the semantics have to be rediscovered and re-encoded every time. Second, mappings are brittle to schema drift. When a source system renames a column, changes a unit, or splits one field into two, every downstream mapping that touched that field has to be found and fixed, often only after a report quietly breaks. Third, and most costly in practice, schema mapping captures structure but not meaning. A column called status in two different systems can encode entirely different concepts, and nothing in a conventional ETL pipeline flags that mismatch — it only becomes visible when a report produces numbers that do not add up, usually well after the data has already been used for a decision.
How a Shared Ontology Creates Meaningful Connections Across Disparate Data Sources
A shared ontology fixes the meaning problem by giving every source system a common vocabulary to map into. In the Common Core Ontologies, a customer record, a shipment record and a support ticket can all be expressed as kinds of Information Content Entity, connected to the real-world things they describe through relations like has_agent or describes. Once two records from different systems are both expressed in those terms, a query can traverse the relation between them even though the original systems never exchanged a single API call directly. The ontology, not a point-to-point pipe, is what makes the connection.
Standing up this kind of cross-system semantic layer is rarely a one-person job inside an existing IT department, and it is not primarily a modeling exercise — it is sustained engineering work to build the pipelines that keep every source mapped correctly as new systems and new data arrive. Most enterprises that go this route end up needing to bring in specialized data engineering teams who already know how to model entities against an upper ontology, wire up ontology-aware ingestion pipelines, and keep the resulting graph consistent as new source systems are added over time.
carrier_status = "DELIVERED" and a support system stores ticket_state = "closed-resolved", with no formal link between them. After: both are mapped to instances of Information Content Entity that describes the same delivery Act, so a query across the two systems can answer "which closed tickets relate to shipments still marked in transit?" without a bespoke join ever being written between the two databases.The Data → Logic → Action Architecture Behind Ontology-Driven Integration
In production, ontology-driven integration is usually organized into three layers rather than treated as a single monolithic graph. The data layer holds records mapped to the shared ontology — the raw facts, expressed in common terms. The logic layer applies rules, constraints and inference on top of that data layer: if an asset is marked as an instance of a particular equipment class and its last inspection date exceeds a threshold, the logic layer can derive that it requires maintenance, even though no system explicitly stored that conclusion. The action layer consumes those derived facts and triggers something concrete — a ticket, a notification, an automated workflow step.
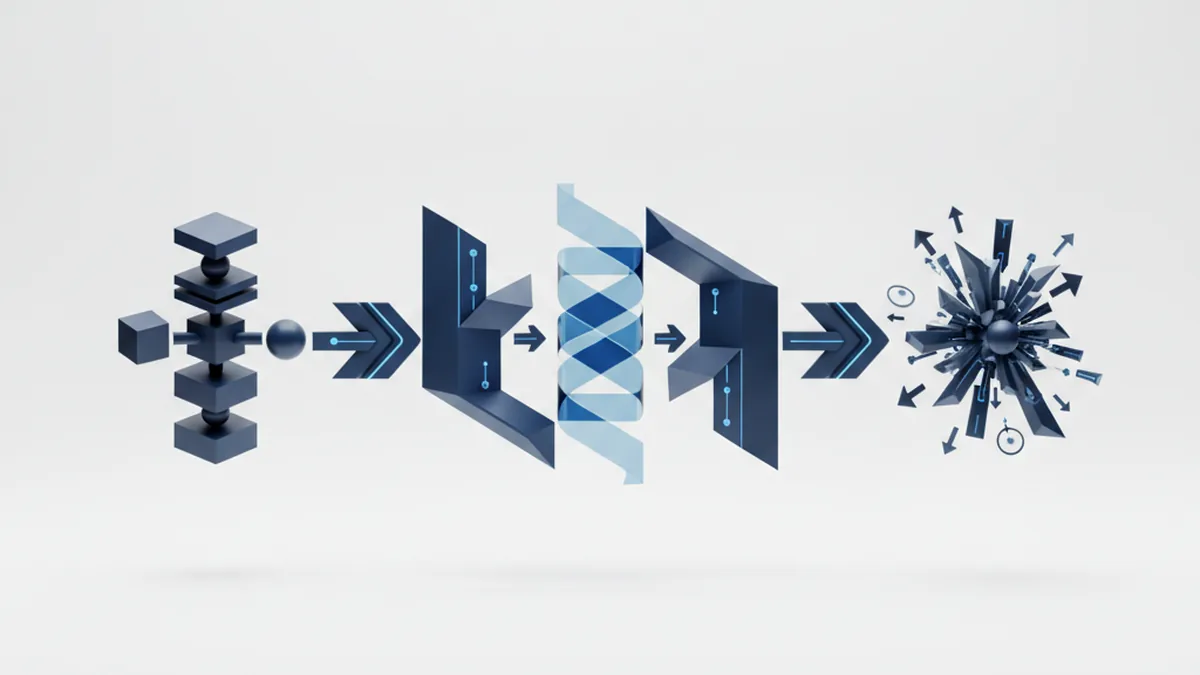
This separation matters operationally because each layer can evolve independently. New data sources are onboarded into the data layer by mapping them to the existing ontology, without touching the logic layer's rules. New rules are added to the logic layer without re-ingesting data. And the system can learn from the outcomes of its own actions — if a maintenance ticket generated by an inferred rule turns out to be a false positive, that feedback refines the rule rather than requiring a change to how data is captured in the first place.
Governance and Security in an Ontology Layer
A semantic layer that spans every system in an enterprise is also a layer that concentrates access to sensitive information, which makes governance a first-class design concern rather than an afterthought. Because every record is expressed as an instance of a well-defined class, access control can be attached at the ontology level: a policy can state that only certain roles may query instances of a Person class linked to specific Information Content Entities, and that rule is enforced consistently regardless of which underlying system the data originally came from.
The same structure that enables fine-grained access control also enables auditability. Every inferred fact in the logic layer can, in principle, be traced back through the relations and rules that produced it — which source records contributed, which rule fired, and which action followed. For regulated industries and for organizations handling classified or otherwise sensitive data, that traceability is often the deciding factor in choosing an ontology-based architecture over a looser integration pattern, because an inference the system cannot explain is a decision the organization cannot defend.
Does Ontology-Driven Integration Scale for Analytics and Cloud Workloads?
Ontology-driven integration scales for analytics and cloud workloads because the underlying representation — a graph of typed entities and relations, typically stored as RDF triples — is designed for exactly the kind of traversal and pattern-matching that large-scale analytics requires. Modern triplestores and graph databases distribute storage and query execution across clusters the same way relational databases do, and cloud-managed graph services have matured enough that standing up a production-scale semantic layer no longer requires running specialized hardware in-house.
The scaling question that matters more in practice is not raw volume but query complexity. A query that traverses many hops across a large graph can be expensive regardless of the underlying infrastructure, so most mature deployments combine the ontology layer with materialized views or pre-computed indexes for the traversal patterns that recur most often, reserving live graph queries for exploratory or lower-frequency analytical work. That combination — a semantically rich graph plus pragmatic materialization — is what lets ontology-driven integration support both ad hoc analytics and high-throughput operational queries on the same underlying model.
Getting Started: A Practical Path to Ontology-Driven Integration
Enterprises that succeed with ontology-driven integration almost never start by trying to model the entire organization at once. A more reliable path looks like this:
- Inventory the systems and the highest-friction connections. Identify which pairs of systems currently require the most manual reconciliation or produce the most data-quality incidents — that friction is where an ontology pays off fastest.
- Choose an upper and mid-level ontology rather than inventing one. Adopting Basic Formal Ontology with a mid-level suite like the Common Core Ontologies means the top-level categories, and the logical consistency behind them, are already solved problems.
- Pick one domain for a pilot. Customer identity, asset records, or a single high-value reporting use case are common starting points because they touch a bounded, well-understood set of systems.
- Map, don't rebuild. The pilot should map existing source systems into the shared ontology rather than replacing those systems, so the integration layer can be evaluated without disrupting operational workloads.
- Expand domain by domain. Each additional domain reuses the ontology's existing classes and relations wherever possible, which is what keeps the marginal cost of each new connection falling instead of rising.
Because this is an engineering program as much as a modeling one, scaling past the pilot is usually where organizations decide whether to grow an internal team or bring in specialized data engineering teams who have already built ontology-aware pipelines elsewhere. Either way, the governing principle stays the same: the ontology should grow to meet real integration needs, not get modeled exhaustively in advance of any system actually using it.
The ontology itself does not need to be built from scratch. The Common Core Ontologies are published as open W3C OWL files on GitHub, and the suite is registered with the OBO Foundry, which reviews ontologies for logical consistency and interoperability with other OBO-registered suites — a useful check before committing an enterprise data architecture to any single vocabulary.
Frequently Asked Questions
What is the difference between an ontology and a data dictionary?
A data dictionary lists field names, types and descriptions for one system, with no formal logic connecting them. An ontology defines classes, relations and axioms that hold across systems, so a reasoner can infer new facts and detect contradictions. A data dictionary documents; an ontology computes.
Do I need Basic Formal Ontology (BFO) to use Common Core Ontologies for integration?
Yes, in practice. CCO is built as a mid-level extension of BFO, and its classes inherit their top-level categories from BFO's distinctions between continuants and occurrents. You do not need to author new BFO content, but your integration layer imports BFO through CCO to stay logically consistent.
Can ontology-driven integration replace my existing ETL pipelines entirely?
Usually not on day one. Most enterprises keep ETL for raw extraction and physical movement of data, then add an ontology-based semantic layer on top that maps extracted records to shared classes and relations. Over time, some point-to-point transformation logic becomes unnecessary and is retired.
How long does it take to see value from an ontology-driven integration project?
Teams that scope a single high-value domain, such as customer identity or asset records, typically see working cross-system queries within a few months. Full enterprise-wide coverage is a multi-year program, but value compounds with each domain added because the shared vocabulary is reused, not rebuilt.
Is ontology-driven integration only for large enterprises?
No. The pattern pays off whenever more than a handful of systems need to exchange meaning, not just data. Mid-sized organizations with a handful of core systems and ambitious data plans often adopt it earlier than large enterprises precisely because fewer existing point-to-point mappings have to be unwound.
What tools are used to query an ontology-backed data integration layer?
Most implementations expose the integrated graph through SPARQL, the W3C query language for RDF and OWL data, often behind a graph database or triplestore. Some teams also layer a GraphQL or REST API on top for application developers who do not need to write SPARQL directly.
Keep reading
Using CCO for data interoperability
Shared meaning is the hard part of joining datasets. A common mid-level ontology is one durable way to get it.
How CCO builds on Basic Formal Ontology
CCO does not invent its top categories. It specialises the domain-neutral distinctions of BFO. Here is how that works.